Recipe · 2× RTX PRO 6000 · with Aevonix Research
GLM 5.3 Flash on two RTX PRO 6000s, with TensorFold.
Serve GLM-5.3-Flash from one Linux host with two 96 GB RTX PRO 6000 Blackwell GPUs, through an OpenAI-compatible API, with 4 concurrent requests, 524,288 tokens a request, tool calling, structured outputs, and image and video input. 238.3 tok/s for one request. The two-GPU sibling of the four-GPU recipe, made with Marc Seal of Aevonix Research: my EXL3 quant and recipe patches, with Aevonix's single-host PCIe work on top. One command builds, downloads, tunes and starts it.
The collaboration
Two labs, one recipe.
This recipe is not mine alone. It was made with Marc Seal of Aevonix Research, and it lives in their GitHub. My GLM 5.3 Flash recipe for DGX Sparks was the starting point: its checkpoint and patches, ported to TensorFold v0.6.5 and taken to one PC over PCIe. This is its two-GPU edition; the four-GPU recipe serves forty requests with FP8 dense layers.
From my lab
- The checkpoint: Mia-AiLab/GLM-5.3-Flash-EXL3-4bpw-TensorFold, my EXL3 quant: routed experts at 4 bits a weight, with the dense layers converted to 4-bit at load time.
- 54 of my recipe patches, ported to TensorFold v0.6.5: dense quantization, the FP8 KV cache, drafting and prompt reuse, concurrent serving, vision, tool calling and API diagnostics.
- The benchmark: every speed below was measured with sparkDash.
From Aevonix Research
- The single-host release and 32 patches of its own.
- One host over PCIe: CUDA IPC exchanges, separate NCCL communicators, prompt lanes and faster prompt kernels.
- One command for one host:
./start.shchecks the host with a clear code for every failure, builds at a pinned commit, downloads, autotunes the kernels and runs a smoke test, built on my two-Spark startup flow.
Performance
Measured, not promised.
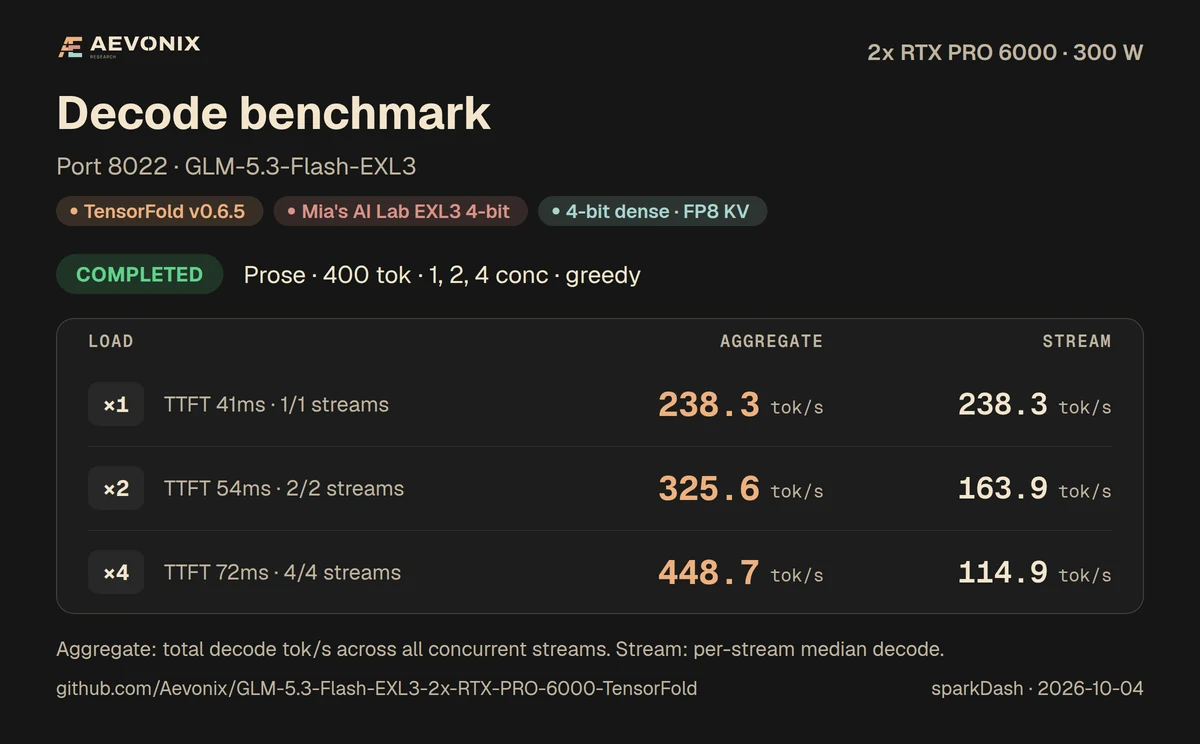
Two RTX PRO 6000 Blackwell Max-Q GPUs at 300 W each, one PCIe host. Measured with sparkDash v1.8.9 on 4 October 2026: greedy, temperature 0, top_p 1, thinking off, 400-token replies, with 4-bit dense layers, the FP8 KV cache, DFlash2 and vision on.
Decode
Aggregate across the concurrent requests, median per request, and median time to first token.
| Requests | Prose | Per request | TTFT | Structured | Per request | TTFT |
|---|---|---|---|---|---|---|
| 1 | 238.3 | 238.3 | 41 ms | 445.0 | 445.0 | 34 ms |
| 2 | 325.6 | 163.9 | 54 ms | 702.9 | 354.1 | 48 ms |
| 4 | 448.7 | 114.9 | 72 ms | 651.2 | 256.7 | 63 ms |
tok/s. With four slots, waves of 8 and 16 requests wait their turn: 423.0 and 424.8 tok/s prose combined. An earlier run at 250 W (TensorFold v0.6.2) measured 226 tok/s for one request and 416 for four.
Code
The same decode measurement, on code.
| Requests | Code | Per request | TTFT |
|---|---|---|---|
| 1 | 350.8 | 350.8 | 48 ms |
| 2 | 486.0 | 247.7 | 64 ms |
| 4 | 584.5 | 163.3 | 327 ms |
Prefill
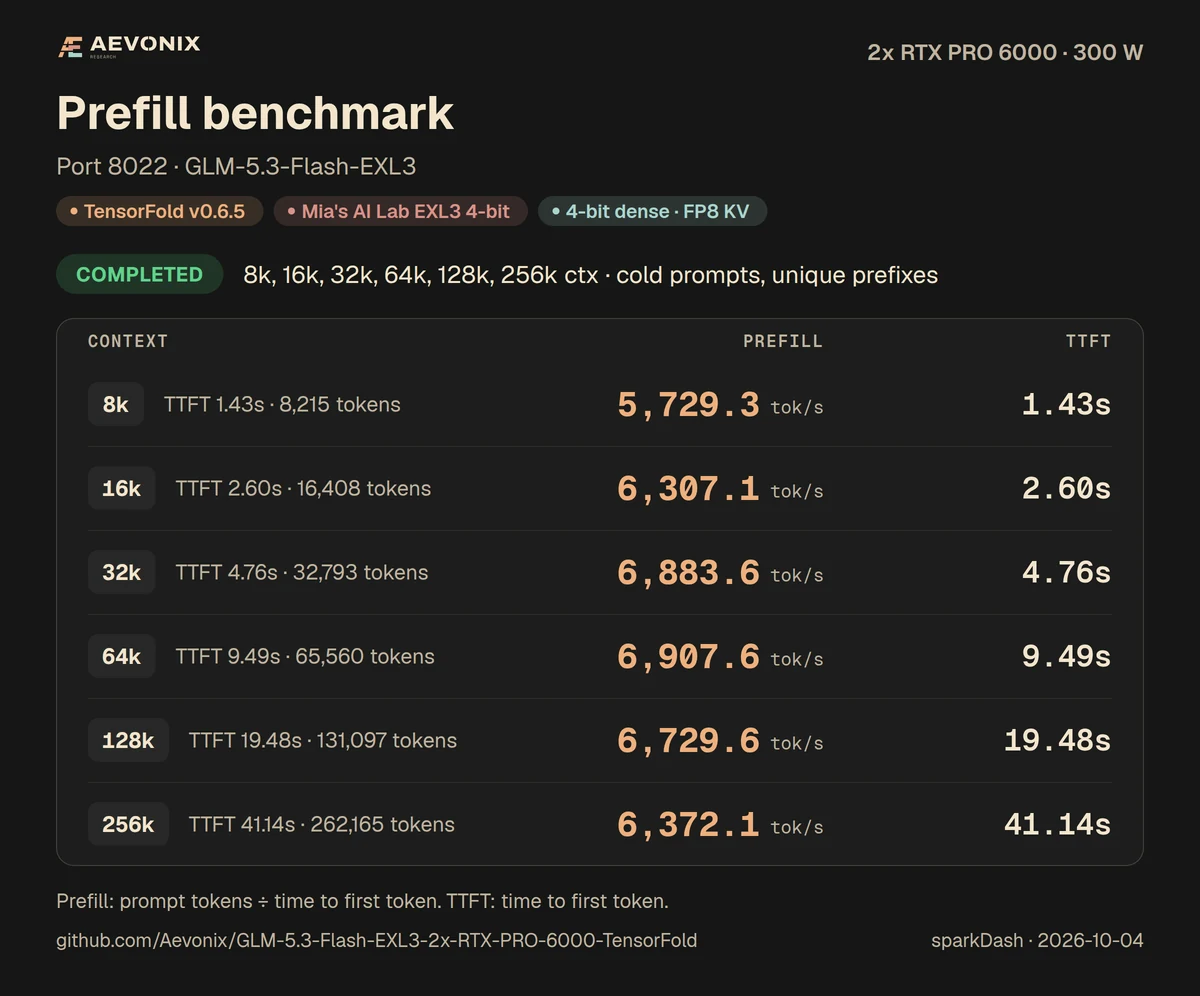
Cold prompts, with a unique prefix per size.
| Prompt | Prefill | First token |
|---|---|---|
| 8,215 tokens | 5,729 tok/s | 1.43 s |
| 16,408 tokens | 6,307 tok/s | 2.60 s |
| 32,793 tokens | 6,884 tok/s | 4.76 s |
| 65,560 tokens | 6,908 tok/s | 9.49 s |
| 131,097 tokens | 6,730 tok/s | 19.48 s |
| 262,165 tokens | 6,372 tok/s | 41.14 s |
Prompt reuse
A conversation's next turn resumes from its kept prompt state instead of reading the whole conversation again. Measured with a separate client workload: the first-time values are the median for three fresh prompts, the next-time values the median for turns 2 to 5 of a conversation that starts near 130K tokens (sampled replies at temperature 0.6). The prompt sizes differ, so these are not matched speedup ratios.
| Prompt | First time | Next time |
|---|---|---|
| 32K-token prompt | 6.16 s | not measured |
| 100K-token prompt | 19.63 s | not measured |
| 140K-token prompt | 27.79 s | not measured |
| A 130K-token conversation's next turn, thinking off | 25.907 s | 0.5115 s |
| A 130K-token conversation's next turn, low effort | 25.341 s | 0.5390 s |
Quality checks
Small, separate checks, not a claim that the model is unchanged. Measured on the v0.6.2 release and not rerun for v0.6.5, whose own validation passed drafted against serial, concurrent against solo, image input and long-context replays.
| Check | Score |
|---|---|
| Tool calls | 40/40 |
| JSON, instruction only | 20/20 |
JSON with response_format | 20/20 |
| Needles at 100K / 200K / 250K / 500K | 3/3 at each |
| Images | 3/3 |
Tool bursts, default choice / required | 78/90 / 90/90 |
| Reasoning effort levels | 4/4 |
Why 4-bit dense layers
Two GPUs have to hold the model, the DFlash2 drafter and the cache, so this edition converts the dense layers to 4-bit at load time. That has a fidelity cost: FP8 dense layers stay closer to the checkpoint's BF16 ones, and FP8 dense was not tested on two GPUs.
The four-GPU recipe uses FP8 dense layers for quality, and shows the measured difference.
The published numbers use 300 W per GPU. The scripts warn when a GPU's power limit differs and never change it.
Speed preview
What 238.3 tok/s feels like.
Sample text played at the measured decode speed, at about four characters a token: one request at 238.3 tok/s, or four at once at 114.9 tok/s each (448.7 combined).
The engine
Powered by TensorFold.
TensorFold, by Ash Hart, is an open-source engine that serves language models on Apple Silicon and NVIDIA GPUs through an OpenAI-compatible API. Each model family brings its own kernels and its own draft verification, tuned for that model instead of one generic path for all.
Exact decoding
Drafts make it fast without changing a word: a draft is accepted only when it equals the token the same engine would produce one at a time. Send a request with "draft": false to compare.
Apple Silicon and NVIDIA
MLX on Macs, and CUDA on NVIDIA GPUs from compute capability 8.9: Ada (RTX 40), Hopper and Blackwell, including the RTX PRO 6000, the DGX Spark's GB10 and the RTX 50 series.
Many model families
GLM-5.3-Flash, Qwen3.8-27B, Qwen3.8 Flash Next, Nemotron 3.5 Lightning, Gemma 4 and DeepSeek-V4-Flash, among others, each with its own kernels.
In this recipe
TensorFold v0.6.5 at a pinned commit, two ranks on one host, with the same 86 patches as the four-GPU recipe: 54 of mine and 32 from Aevonix Research, with launch tables tuned for two GPUs and a 32-row verify window for four concurrent requests.
What you need
Two GPUs, one host.
Two RTX PRO 6000s
Two 96 GB RTX PRO 6000 Blackwell GPUs in one Linux x86_64 host, working NVIDIA drivers, and CUDA peer access between them. Keep them idle for the first compile and the kernel autotune.
Free GPU memory
At least 90,000 MiB free on each GPU at launch (about 88 GiB). The defaults keep 6 GiB in reserve on each GPU and cap the spare KV cache at 3.75 GiB a GPU; the engine checks that the window fits.
Docker
Docker with the NVIDIA Container Toolkit, and your user in the docker group. Plus Bash, Python 3, Git, GNU patch, curl, gzip and flock. A Hugging Face token is optional.
Disk
Budget 180 GiB for the checkpoint, 10 GiB for DFlash2, 40 GiB for the image and build and 10 GiB for kernels. The script adds them up when they share a filesystem.
Quick start
One command, start to finish.
Clone and start
git clone https://github.com/Aevonix/GLM-5.3-Flash-EXL3-2x-RTX-PRO-6000-TensorFold.git
cd GLM-5.3-Flash-EXL3-2x-RTX-PRO-6000-TensorFold
./start.sh
The first run checks the host, builds TensorFold at the pinned commit with all 86 patches, downloads the checkpoint and the drafter, compiles the kernels and runs the one-time autotune of the two-GPU launch table. That takes a while and needs idle GPUs; later runs reuse what is ready. It sends a short smoke request and prints GLM-5.3-Flash-EXL3 is now LIVE! on port 8022.
DRY_RUN=1 ./start.sh          # see every step and command first, without Docker or GPUs
DRAFTER=mtp ./start.sh        # without the non-commercial DFlash2 drafter (one request at a time)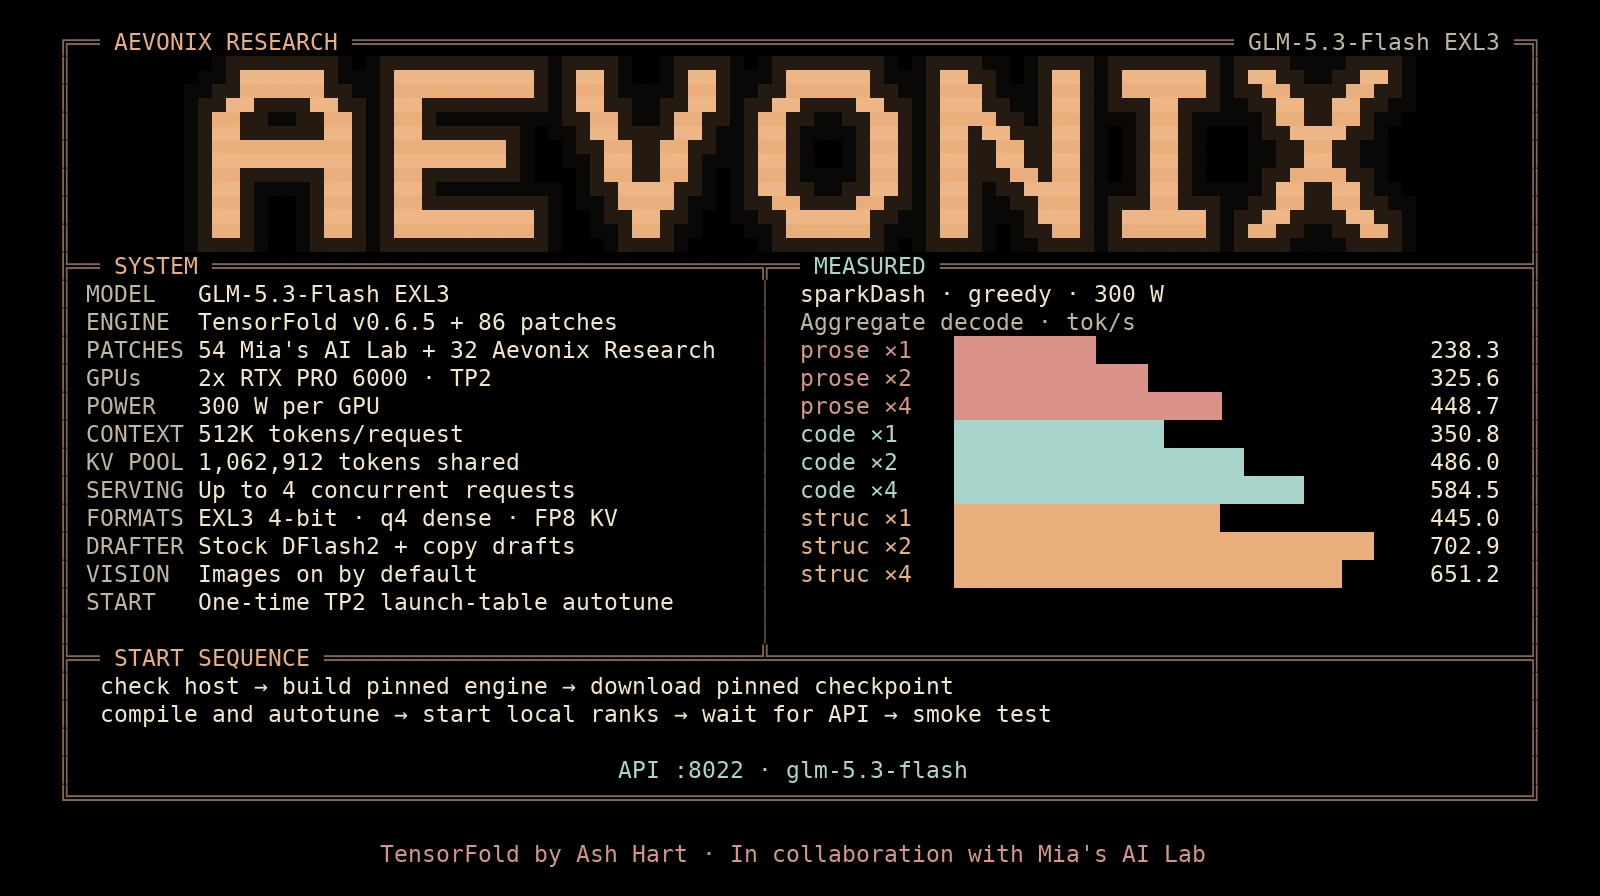
Talk to it
Any OpenAI client works with base_url = "http://<host>:8022/v1" and the model glm-5.3-flash. Thinking is off by default; a request turns it on with "chat_template_kwargs": {"enable_thinking": true}.
curl -s http://127.0.0.1:8022/v1/chat/completions -H 'Content-Type: application/json' -d '{
  "model": "glm-5.3-flash",
  "messages": [{"role": "user", "content": "Write a Python fibonacci function."}],
  "temperature": 0,
  "max_tokens": 2000
}'
./start.sh restart # restart, e.g. after changing a setting
./stop.sh # stop, and save the logs under logs/
docker logs -f glm53-tf-2x # follow the server
curl -s http://127.0.0.1:8022/healthIf start.sh stops at a check
Every failed check prints a code. The ones you are most likely to see:
| Code | What to do |
|---|---|
E_GPU_BUSY / E_GPU_MEMORY | Other work is on the GPUs: stop it. Each selected GPU needs at least 90,000 MiB free. |
E_P2P | CUDA peer access failed: check the driver and the platform's PCIe topology, ACS and IOMMU settings. The two GPUs must support peer access. |
E_DOCKER_GROUP | Add your user to the docker group and log in again. |
W_POWER | The power limit isn't 300 W, so results may differ. The script never changes it. |
E_AUTOTUNE | Read the compiler error, leave the GPUs idle and rerun. Incomplete tuning is never marked ready. |
The full list, with every code, is in the README.
Images and video
It can see, too.
Vision is on by default. Send images and videos as OpenAI-style content parts in a user message: an image_url part, or a video_url part for a clip. The vision tower runs on rank 0.
| Input | Content part |
|---|---|
| Image | {"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,..."}} |
| Video | {"type": "video_url", "video_url": {"url": "data:video/mp4;base64,..."}} |
Only data URLs are accepted; outside media URLs are off. VISION=0 serves text only.
Memory
Half a million tokens a request, four requests.
All requests share one FP8 cache pool of 1,062,912 tokens (measured), shared with the drafter. A capacity check accepted a 524,280-token prompt with an 8-token reply budget. Any one request can use the full 524,288-token window, but four full windows at once are not promised. /health shows pool_tokens and pool_free_tokens, and the engine refuses a window that doesn't fit instead of shrinking it.
| Setting | Default |
|---|---|
Concurrent requests (PARALLEL) | 4 |
Prompt plus reply (CONTEXT) | 524,288 tokens a request |
KV cache (KV) | FP8 |
| Memory reserve / spare KV cap | 6 GiB / 3.75 GiB a GPU |
Settings
The ones you might change.
Settings come from the environment, then scripts/local.sh, then .env, then the defaults in scripts/config.sh. Set one for a single run (PORT=9000 ./start.sh restart), or keep it in scripts/local.sh. The full list is in the README.
| Variable | Default | Meaning |
|---|---|---|
PARALLEL | 4 | Concurrent requests (1 with MTP); larger settings need their own memory and exactness checks |
CONTEXT | 524288 | Prompt plus reply tokens per request |
DENSE | q4 | 4-bit dense layers; fp8 and the checkpoint's bf16 are untested on two GPUs |
KV | fp8 | KV cache; bf16 needs more memory |
DRAFTER | dflash2 | Inco AI's DFlash2 drafter (non-commercial use only), or mtp, the checkpoint's own MTP head, one request at a time |
THINKING / REASONING_EFFORT | 0 / high | Thinking off by default, and its effort when a request turns it on |
MAX_TOKENS | 32768 | The reply budget when a request doesn't set one |
VISION | 1 | Image and video input |
GPUS / PORT / HOST | 0,1 / 8022 / 0.0.0.0 | The two GPUs (a pair with CUDA peer access), and the API's port and address |
The API
/v1/chat/completions with the model glm-5.3-flash, /v1/models, /tokenize and /detokenize, /health and Prometheus /metrics. Tool calling (complete calls streamed, arguments typed by their schema) and structured outputs (json_object or json_schema, enforced with xgrammar). A sampled request without top_k is served with 20; send top_k to compare with another engine.
Exact replies
The checks compare drafted replies with serial ones, concurrent requests with solo ones, and long prompts with saved token hashes, all within one fixed configuration. 4-bit dense layers, the FP8 KV cache and chunked KDA change the arithmetic, so passing the checks doesn't mean the output matches BF16 or the original model; the quality checks above are measured for that.
Licenses
Free, with a few rules.
- The recipe, its code and documentation, is Apache License 2.0. Upstream code and model weights keep their own licenses.
- The checkpoint, Mia-AiLab/GLM-5.3-Flash-EXL3-4bpw-TensorFold, is under the Apache License 2.0.
- The DFlash2 drafter is CC BY-NC-ND 4.0, non-commercial use only, and is not redistributed by the recipe.
DRAFTER=mtpserves without it. - TensorFold is Apache 2.0; its earlier code keeps its MIT notices.
- The base model, GLM-5.3-Flash, is by Z.ai.
Credits
Built together, on the work of others.
- Marc Seal and Aevonix Research: the single-host release and its 32 patches
- My lab: the EXL3 checkpoint, the original recipe and 54 of its patches, and sparkDash
- TensorFold by Ash Hart
- GLM-5.3-Flash by Z.ai
- The DFlash2 drafter by Inco AI
- The EXL3 format (ExLlamaV3) by turboderp
- b12x by local-inference-lab, and glm53-tensorfold-spark by Jay Leaton
The full list is in the recipe's CREDITS.md.
Run it on your two GPUs.
Free and open, with every patch and every number published.