Mia’s Favorite
GLM 5.3 Flash
TensorFold Zig · EXL3 4-bit · DFlash2
47.8 tok/s
Decode speed, one stream
- Peak
- 87.3 tok/s ×4 streams
- Prefill
- 1,801 tok/s 32k prompt
- Context
- 1M · a ~2.1M shared pool
0 stars0 forks1 contributor
Last updated
I run open-weight and frontier models side by side, same prompt, one shot each, and publish every raw output. See what they build, and where they break.
New recipe · two DGX Sparks
A million tokens of context, images and video, and up to sixteen conversations at once, served from two Sparks on your desk with TensorFold's Zig engine. Run NVIDIA's NVFP4, or the faster INT4-AutoRound at 89.3 tok/s. Free, with every patch and every number published.
Found the needle in a 998,986-token prompt.
See all recipesNew research · In validation
About
I'm a developer who got hooked on running AI locally. Most days I'm deploying and optimizing local AI models to run the BEST way possible for NVIDIA DGX Sparks and other devices I have in my lab.
From GLM, DeepSeek, Qwen, and others, I deploy them all, and make them work at their best state possible on the available hardware.
I'm also comparing and benchmarking all closed frontier AI models, including Claude, GPT, Grok and others, to see how they compare to the best local has to offer.
Models offered
Each recipe runs on my own Sparks, and the benchmarks, patches and launch scripts are all published on GitHub. Clone one and serve a frontier-class model on your own hardware.
Across 28 recipes and sparkDash
Mia’s Favorite
TensorFold Zig · EXL3 4-bit · DFlash2
47.8 tok/s
Decode speed, one stream
0 stars0 forks1 contributor
Last updated
Mia’s Favorite
TensorFold Zig · FP8 + MXFP4 · DSpark
65.8 tok/s
Decode speed, one stream
59 stars19 forks11 contributors
Last updated
vLLM · NVFP4
48.7 tok/s
Decode speed, one stream
627 stars89 forks8 contributors
Last updated
Plus 25 more recipes for DGX Sparks and NVIDIA GPUs, and sparkDash, the dashboard I benchmark with.
New in the Lab · Projects
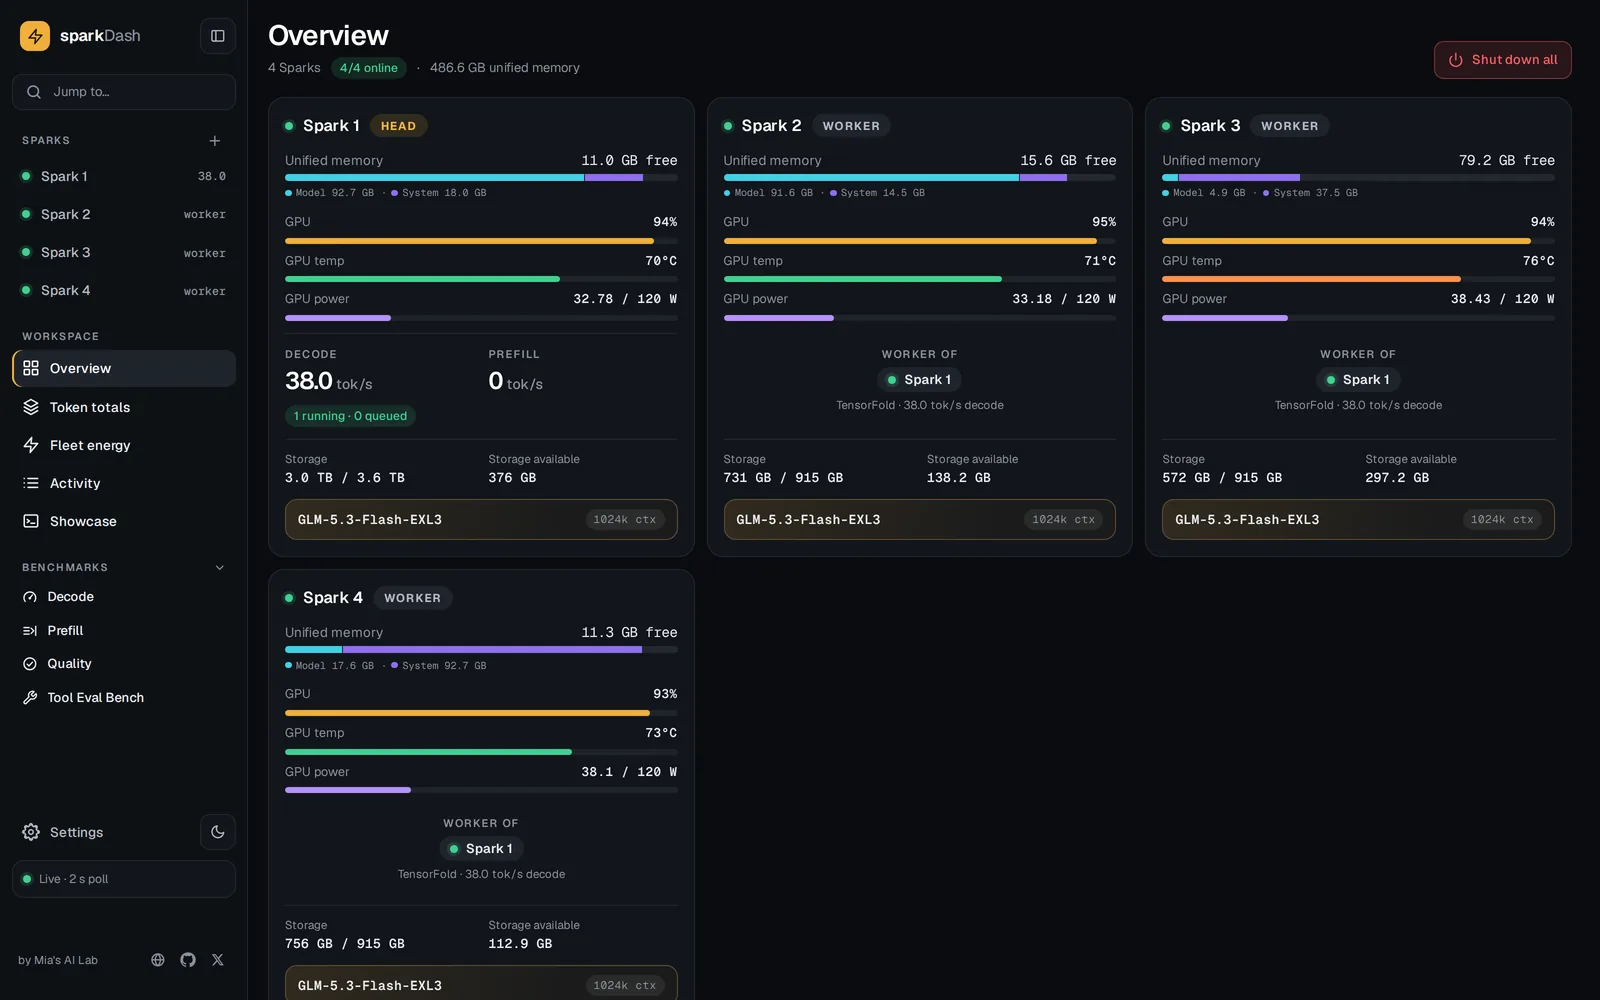
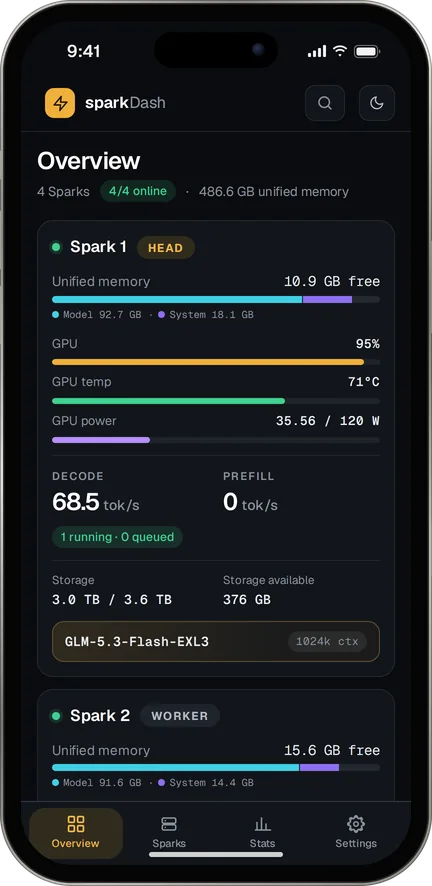
My open-source dashboard for NVIDIA DGX Sparks and NVIDIA GPU machines, and the benchmark behind every speed on my recipe pages. New in 2.70: alert notifications to ntfy, Discord or Slack, 30 days of metrics history, a cost compare page, and NVIDIA Flare support.
New in the Lab · Grok Bots
Small Grok bots I build for my own lab and publish for free. Each one does a single job in the background, so you can stay on the work that matters.
Meet the Grok BotsSupport & contact
Everything here is independent. Donations pay for GPU time, API credits and the coffee behind late-night runs.
or donate with crypto
Donate with crypto through NOWPayments. Pick an amount and a coin, and you'll finish the payment on their secure checkout.
A question, a model you want tested, a collab idea? I read every message.
or find me on